PROJECT FILE / NeurIPS 2026
GEAR
Scale global optimization by batching proof work and reusing linear bounds throughout search.
GEAR: A GPU-Accelerated Global Solver for Bounded Continuous Nonlinear Programs via Linear Bound Propagation
Duo Zhou, Hesun Chen, Xiangru Zhong, Grani A. Hanasusanto, Huan Zhang
Accepted to NeurIPS 2026. arXiv · PDF · OpenReview · Read the research note
Two ways to make global search scale
A global optimizer may need to examine thousands or millions of subdomains before it can certify a solution. Its runtime depends on both the cost of processing each domain and the number of domains that survive its bounds:
Classical global NLP solvers reduce by solving polyhedral LP relaxations at each node, strengthened with McCormick envelopes, optimization-based bound tightening (OBBT), and Reformulation-Linearization Technique (RLT) cuts. Variable cut counts and irregular active sets keep those per-node subproblems on the CPU. GEAR makes the opposite architectural trade: it propagates a single affine lower bound per output so that a frontier of heterogeneous boxes shares fixed tensor shapes and . It then recovers pruning and primal-search strength by making every stage of node processing reuse those same linear coefficients (Paper, Sections 1 and 3).
Turn the search frontier into a tensor workload
GEAR compiles the objective and all shifted inequality constraints into one multi-output computation graph . Linear constraints need no relaxation and are substituted exactly by linear bound propagation (LBP). A backward propagation pass is vectorized over both the outputs and the branch-and-bound boxes: each box retains its own interval bounds and linear coefficients while sharing the graph’s computational structure.
One set of propagated linear bounds serves five roles across the solver without constructing a separate LP model for each operation (Paper, Figure 1 and Sections 3.2–3.5):
| Reuse of the same linear bounds | Effect on global search |
|---|---|
| Constraint relaxations and domain clipping | Relaxed clipping shrinks input box coordinates in per box; complete clipping tightens intermediate intervals over the linearized constraint polyhedron . |
| Lagrangian lower bound | Dualizes over the box via for , evaluated in closed form in per box and tightened by projected Adam and batched GPU PDHG. |
| Incumbent-independent infeasibility certificates | Certifies whenever for , using unit vectors or Farkas multipliers from a phase-one violation LP. |
| Dual-guided projected ALM primal search | Starts batched first-order augmented Lagrangian updates from the Lagrangian inner minimizer and initializes ALM multipliers by rescaling . |
| Multiplier-weighted smart branching (-SB) | Scores coordinate by to pick midpoint splits without bounding candidate children. |
Projected augmented Lagrangian updates, Gauss–Newton feasibility restoration, and Mehrotra SQP polish also execute as batched GPU computations (Paper, Section 3.4 and Appendix B.6), keeping primal recovery in the same throughput regime as dual bounding.
Stronger bounds make throughput useful
An inexpensive bound becomes useful only when it can retire a domain. Inherited constraint rows remain valid on child boxes, allowing each child to be clipped immediately before running its own propagation pass; fresh nonlinear rows then replace the inherited ones so per-box memory does not grow with tree depth (Paper, Section 3.5 and Appendix A.3).
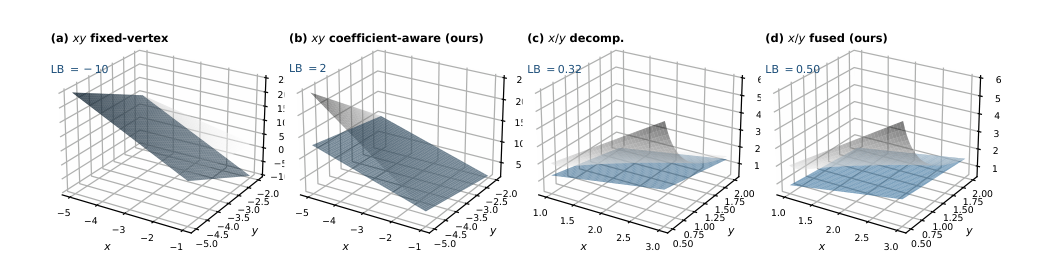
Because LBP keeps one affine plane per operator output, local envelope quality directly determines downstream tightness (Paper, Section 3.3 and Appendix A.7):
- Bilinear products (): Instead of fixing one McCormick vertex, GEAR compares the two lower (or upper) McCormick facets by closed-form box concretization according to the backward coefficient sign. On , coefficient-aware selection raises the lower bound from to (Figure 4a,b).
- Quotients (): On sign-fixed guarded denominator intervals, GEAR scores an 8-plane candidate pool (four corner tangents and four three-corner secant planes) directly on and accepts a plane only after a quadratic-bilinear residual check . On , fusing division lifts the lower bound from to (Figure 4c,d).
- Univariate and trigonometric primitives: Parallel secant-tangent relaxations match the tangent slope to the secant slope, cutting the tangent-side bound gap by 26% for , 27% for , 31% for , and 23% for over midpoint tangents (Paper, Figure 3), while exact graph rewrites (completing squares, , quadratic eigenbasis and log-coordinate posynomial rewrites) and a lifted linear relaxation strengthen root and tree certificates (Paper, Appendices B.1–B.4).
The paper’s cumulative ablation across all 505 instances under the 180-second limit separates primal discovery from dual certification (Paper, Section 4.2, Table 2):
| Configuration (505 instances, 180 s limit) | Feasible | Optimal* | Solved | Change in Solved |
|---|---|---|---|---|
| Bound propagation + PGD (verification baseline) | 95 | 56 | 0 | — |
| + presolve and CPU solving components | 480 | 396 | 219 | +219 |
| + projected ALM primal search (GPU) | 496 | 471 | 269 | +50 |
| + constraint-aware dual bounds and clipping (GPU) | 498 | 472 | 366 | +97 |
| + lifted and refined operator relaxation (GPU) | 501 | 478 | 410 | +44 |
| + -SB branching (full GEAR) | 501 | 478 | 421 | +11 |
The standard neural network verification pipeline (Bound propagation + PGD) solves 0 instances: a box PGD attack looks for a counterexample without enforcing nonlinear constraints, so even though it hits the optimal value on 56 of the 95 box-constrained problems, it keeps no verified feasible incumbent as a pruning threshold. Once presolve and GPU projected ALM are added, GEAR already holds a feasible point within of the best known optimum (Optimal*) on 471 of 505 instances, with 269 certified. The remaining components—constraint-aware dual bounds and clipping (+97, the single largest GPU step), lifted and refined operator relaxations (+44), and -SB branching (+11)—raise the certified solved count from 269 to 421 (+152) while adding only 7 optimal points (). They finish the optimality proof rather than merely finding better points.
Where GPU-batched bounds beat per-node LP strength, and where they do not
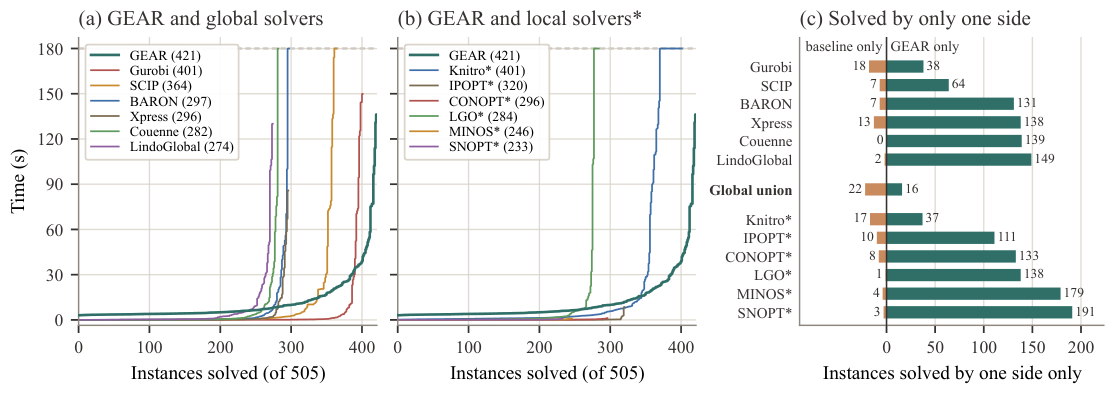
Across 505 bounded continuous NLP instances (265 from gams_world and 240 from minlplib) on a single workstation (AMD Ryzen 9700X, 256 GB RAM, NVIDIA RTX 5090) under a 180-second limit, absolute feasibility tolerance , and relative optimality gap , GEAR certifies 421 of 505 instances (83.4%) and returns a feasible point on 501—more than each of the six global solvers and six local solvers compared (Paper, Section 4.1, Table 1):
| Solver | Category | gams_world Solved / 265 | minlplib Solved / 240 | Total Feasible / 505 | Total Solved / 505 | Solved (%) |
|---|---|---|---|---|---|---|
| GEAR | Global (GPU + CPU) | 251 | 170 | 501 | 421 | 83.4% |
| Gurobi | Global (commercial) | 227 | 174 | 472 | 401 | 79.4% |
| SCIP | Global (open-source) | 209 | 155 | 481 | 364 | 72.1% |
| BARON | Global (commercial) | 168 | 129 | 403 | 297 | 58.8% |
| Xpress | Global (commercial) | 176 | 120 | 391 | 296 | 58.6% |
| Couenne | Global (open-source) | 182 | 100 | 374 | 282 | 55.8% |
| LindoGlobal | Global (commercial) | 164 | 110 | 349 | 274 | 54.3% |
| Knitro* | Local (matched to global bound) | 231 | 170 | 488 | 401 | 79.4% |
| IPOPT* | Local (matched to global bound) | 203 | 117 | 458 | 320 | 63.4% |
Against the strongest global baseline, Gurobi (401), GEAR certifies 38 instances that Gurobi does not while Gurobi certifies 18 that GEAR does not; against SCIP (364), the exclusive split is 64 to 7. Across all six global solvers individually, GEAR certifies 38–149 instances that each baseline misses against 0–18 in the reverse direction. Against the union of all six global solvers (427 instances), GEAR certifies 16 instances solved by none of the six global solvers and misses 22, bringing combined portfolio coverage to 443 of 505 (Paper, Section 4.1, Figure 2).
The problem-class breakdown (Paper, Section 4.1 and Appendix D, Tables 10–11) shows where the GPU-batched regime wins and where classical LP branch-and-bound still dominates:
- Low- to medium-dimensional problems with composite transcendental nonlinearities: GEAR pays a startup cost of a few seconds for graph compilation and GPU initialization, overtaking LindoGlobal, Couenne, BARON, and Xpress at 6–9 s, SCIP at 15 s, and Gurobi at 35 s. Its lead comes from the hard tail: GEAR certifies 322 of 330 instances (97.6%) with at most 20 constraints (vs. 298 for Gurobi and 278 for SCIP) and 131 of 147 instances (89.1%) containing transcendental terms (vs. 110 for Gurobi and 100 for SCIP). All 16 instances certified by GEAR and by none of the six global solvers contain exponential, logarithmic, or trigonometric terms. GEAR closes 293 of its 421 solved instances at the root (including 12 of those 16) and 128 in the GPU branch-and-bound tree (median 318 boxes, with at least boxes on five instances).
- Large structured bilinear models: On instances with more than 20 constraints (pooling, wastewater, water networks, and
kallcircle packing), Gurobi certifies 103 of 175 against 99 for GEAR, and 20 of the 22 Global-union-only instances fall into this class. On the 16 bilinear QCQPs where Gurobi or SCIP wins and GEAR does not, Gurobi re-solves warm-started LPs with RLT and cuts at to nodes per second, whereas GEAR solves no instance with more than 1,000 variables.
GEAR targets bounded continuous programs over supported factorable operators; mixed-integer and unbounded programs are outside its scope. Pruning uses conservatively evaluated lower bounds and Farkas certificates, and primal candidates update the incumbent only after direct verification on the original constraints at . The research note develops the dual-primal coupling, the operator envelopes, the ablation analysis, and the structural regime boundary in detail; the verification project traces the linear bound propagation and domain clipping machinery this solver builds on.
Cite the paper
@article{zhou2026gear,
  author        = {Zhou, Duo and Chen, Hesun and Zhong, Xiangru and Hanasusanto, Grani A. and Zhang, Huan},
  title         = {{GEAR}: A {GPU}-Accelerated Global Solver for Bounded Continuous Nonlinear Programs via Linear Bound Propagation},
  journal       = {arXiv preprint arXiv:2611.10487},
  year          = {2026},
  eprint        = {2611.10487},
  archivePrefix = {arXiv},
  primaryClass  = {math.OC},
  url           = {https://arxiv.org/abs/2611.10487}
}